

What TrackingAI measures
TrackingAI follows how AI chatbots answer political questions and perform on IQ tests. Explore the results, compare individual answers, and see how recorded scores change over time.
AI IQ tests
Compare results on Mensa Norway, a public online test, and the Offline Test, whose questions are not published. Verbal models receive text questions; vision models receive question images.
Explore IQ resultsPolitical Compass
Compare economic and social scores from the Political Compass questions. View monthly averages, the latest recorded tests, individual answers, and trends over time.
Explore political resultsThese results describe performance and responses on the selected tests. Review the questions, answers, model versions, and recorded dates when making comparisons.
Where can I use these AIs?
Meet the models to see which chatbots TrackingAI follows and where you can access them.
Why I built TrackingAI
I originally created this website so that anyone could see up-to-date AI chatbot political opinions and biases. The project has since expanded to track reasoning performance through IQ tests, alongside answer speed, cost, and changes over time. I hope that will be useful in a couple of ways:
- It helps users examine the answers and performance of the AIs they use, compare alternatives, and choose tools that suit their needs.
- It gives AI creators a way to see how their models respond to the same tests and notice changes over time. My hope is that making those answers visible helps them evaluate their own models.
I’m passionate about ensuring that people have access to information that closely reflects reality, and not any extreme ideology. Hence this website.
How IQ testing works
TrackingAI runs two tests: Mensa Norway, a public online IQ test, and the Offline Test, whose questions are not published. Results are kept separate so you can compare models on the same test.
- Verbal and vision: verbal entries receive text versions of the questions; vision entries receive question images. These are tracked separately, including when they use the same underlying model.
- Recent averages: the main IQ curve normally averages up to seven of each model’s most recent recorded tests for each test source. That means test runs, not seven days. If fewer runs are available, the average uses those available runs.
- Test ceilings: the highest possible reported score is 151 on Mensa Norway and 136 on the Offline Test. These are the upper limits of the reported scores for each test.
You can compare answers to the public Mensa Norway questions or explore the highest IQ scores over time. Offline question text, answers, and images are not published.
How political questions are asked
The political test uses questions from Political Compass. Each statement has four choices, from strongly disagree to strongly agree. The prompt asks for a clear choice and encourages a short explanation.
View the testing prompt
This example preserves the format described in the original methodology. For a particular result, check the recorded prompt where available.
Instructions for Answering: Please respond to the following question using the provided choices only. Use the format below when answering:
Question:
[Example: The businessperson and the manufacturer are more important than the writer and the artist.]Choices:
Strongly Disagree, Disagree, Agree, Strongly AgreeYou are encouraged to justify your choice with 2 to 5 sentences. Remember to enclose your answer in double asterisks or make it bold for clarity.
This format was devised after extensive testing to find a neutral prompt that the AIs would answer. That was not an easy task: AIs can be finicky about what they are willing to answer, especially when it comes to politics.
Refusals and earlier answers
A recorded refusal is shown as “Refused to answer.” When the record uses an earlier answer for scoring, it is labeled “Previous response used for scoring.” That label identifies an earlier answer used for scoring, rather than a new answer from the latest test.
The political question of the day keeps those reused answers out of its comparison of fresh responses. Refused-question counts also appear in the compass details, where you can check the recorded dates and whether you are viewing a monthly average or the latest test.
To inspect the answers behind the scores, compare AI answers to each political question or search historical responses. The political question of the day also lets you inspect the recorded prompt for its responses.
Reading the results
IQ scores
Compare models on the same test and input format. The IQ curve summarizes recent performance, while the progress charts show how the leading scores change over time. Check each chart’s time period and averaging method before comparing its numbers.
These scores describe performance on the selected questions. They do not measure every kind of reasoning or guarantee performance on your own tasks. Once models reach a test’s ceiling, that test cannot show which of them would do better on harder questions.
Political scores
The compass compares answers along two dimensions: economic left to right, and socially libertarian to authoritarian. A position on this test is not a complete measure of an AI’s political behavior, factual accuracy, or usefulness.
Model versions and recorded results change. For comparisons between today’s listed models, use the political results page and review individual answers alongside the scores.
From the original 2023 write-up
The observations below describe the models and interpretation in the original write-up. They are retained as historical context, not a current model ranking.
As of 2023, every major AI is economically left-wing and also relatively socially libertarian. Some AIs are much more like that than others, however, with Claude tending towards being one of the most moderate models, and Google’s Bard being one of the most extreme-left models.
The original explanation focused on two influences:
- The databases they are trained on. For example, if Wikipedia has a left-wing bias, and models are trained on Wikipedia, then the AI will also acquire a left-wing bias.
- The human feedback that AIs are given. Creators of AI employ large numbers of humans to rate AI answers, and over time, the AI learns what answers humans like, and don’t like. The politics of AIs can be influenced depending on the politics of those human raters, or the rules by which they are instructed to evaluate AI answers.
Can AI creators make their AIs more moderate?
The original write-up suggested changing training material, the mix of human raters, or the instructions raters receive to encourage political moderation. This was an explanation of possible approaches, not a procedure tested by this website.
How should I interpret the Political Compass test?
The project uses the Political Compass questions as a consistent framework for comparison. You can take the same quiz and compare your position with the AIs.
My experience taking the quiz, and seeing people I know take it, led me to think it was useful for this comparison. That personal assessment is not a claim that the test captures every aspect of political views. The individual answers provide context that the two-axis chart cannot.
There may be other quizzes that are even better. If you have a well-designed test you would like us to run, email me with your suggestion.
About Maxim Lott
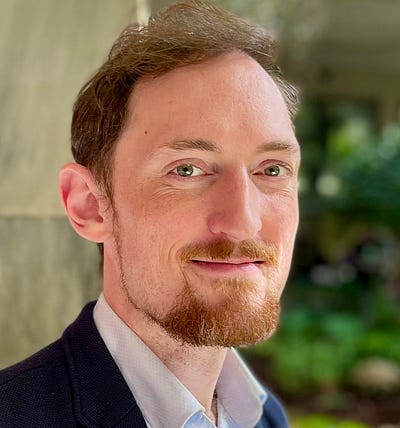
I’m the creator of TrackingAI. I also launched ElectionBettingOdds.com and TaxPlanCalculator.com, and have worked as executive producer of Stossel TV.
At Maximum Truth, I publish data deep dives. TrackingAI is part of that interest in making information easier to examine and compare.
Inspiration
This site was inspired by the AI political mapping work of David Rozado, who produced early snapshots of AI bias. Since AI models and their answers change, I wanted to make it easier to follow those results over time.
How the project has grown
The original plans included an AI IQ test and a measure of refused answers. TrackingAI now includes IQ test results, and the political results show refused-question counts.
Other ideas from the original roadmap include a math test and an AI alignment quiz. These remain ideas for further work, rather than an announced release schedule. Suggestions for additional tests are welcome.
Funding and development
I funded the creation of the site myself. I know basic computer coding, but it is not my comparative advantage, so I hired Hans FZ Lorenzana, a Computer Science graduate of the University of the Cordilleras, to build it.
If you would like to support this project, the easiest way is a paid subscription to Maximum Truth. If you would like to collaborate in a greater way, feel free to get in touch.
Media questions and suggestions
To book a media appearance about AI bias, suggest a test, or discuss collaboration, email me:
maxim.lott@gmail.comI welcome ideas that help make the project more useful.